
OpenAI states that its Generative Pre-trained Transformer 6 model is far better at handling legacy programming languages such as Common Business-Oriented Language and Fortran.
OpenAI's generative models score about 87% on MultiLangBench and COBOL migration, showing big gains for legacy low-resource programming languages.
Key Takeaways
- OpenAI says its GPT-6-class models, especially GPT-6 Astra and GPT-6.1 Sol, show major gains on low-resource programming languages such as COBOL, Fortran, and Visual Basic.
- The evaluation uses two benchmarks: MultiLangBench, which tests database-building across 20 languages, and a COBOL migration test that translates legacy COBOL code into modern languages.
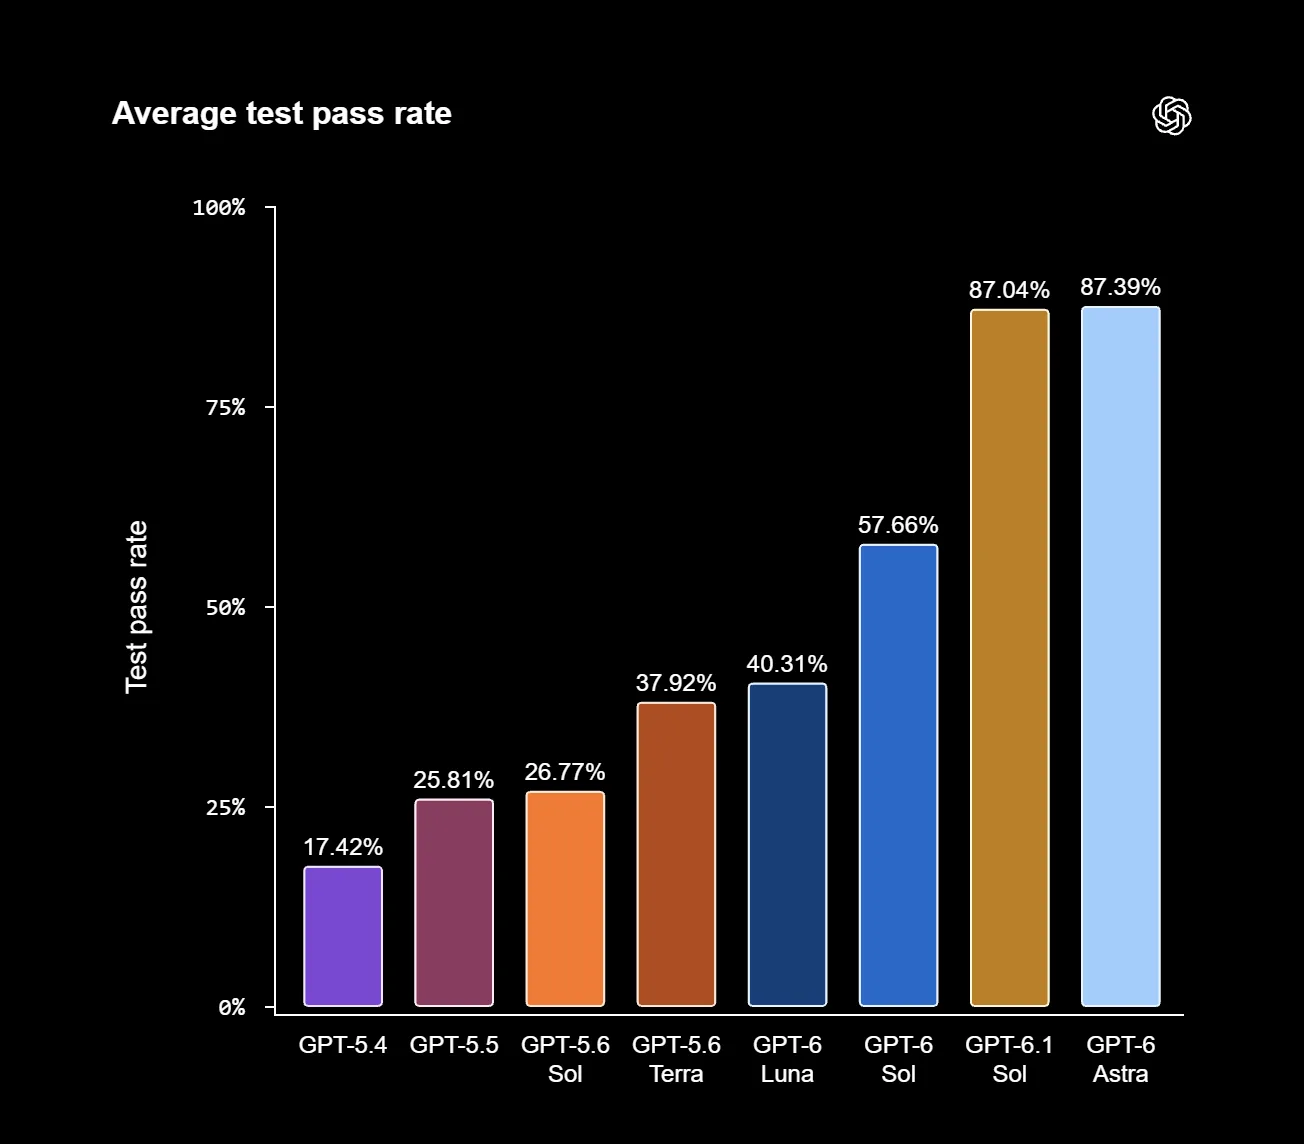
- GPT-6 Astra reaches about 87.4% on MultiLangBench, far above GPT-5.6 Terra’s roughly 38%, while GPT-6.1 Sol also scores around 87%.
- On COBOL migration, GPT-6.1 Sol achieves 86.6% accuracy at low reasoning effort and up to 97.9% with higher reasoning effort, compared with 5.4% for GPT-5.6 Sol.
- The progress matters because COBOL still supports critical systems such as banking and ATM transactions, though real-world reliability across legacy infrastructure remains unproven.
Meta Description: OpenAI's GPT-6 Astra and GPT-6.1 Sol score about 87 percent on MultiLangBench and COBOL migration tests, showing progress on low-resource languages.
Tags: OpenAI, GPT-6, low-resource languages, COBOL migration, MultiLangBench
Featured Image: Abstract technology style image of legacy code paths converging into modern language targets, no real people, no company logos, no text.
OpenAI's GPT-6 models for low-resource languages moved sharply forward on two new evaluations, with GPT-6 Astra and GPT-6.1 Sol reaching about 87 percent on tasks that older models largely failed. The results matter because COBOL, Fortran, and Visual Basic are not widely represented in public training code, yet OpenAI says they support critical infrastructure worldwide.
Legacy Code and Limited Training Data Set the Stage
Systems written in COBOL, Fortran, and Visual Basic have remained embedded in important services for a long time. The amount of available code for training language models in these languages is far smaller than for Python, which creates a low-resource problem: newer systems have less text to learn from, but the languages still underpin everyday infrastructure.
IBM's estimates show why that imbalance has real-world weight. The company says COBOL powers more than 40 percent of online banking systems and 95 percent of all ATM transactions. Those figures make progress in older programming languages more consequential than it might first appear, even when the training data is limited.
Two Evaluations Track Capability Gaps
OpenAI built two tests to measure whether newer models can handle this kind of work. The first is MultiLangBench, listed on GitHub. It asks a model to create a SQLite-compatible database engine from scratch and reports the average test pass rate across 20 programming languages.
The second benchmark is a COBOL migration test. It translates COBOL code into C++, Java, Kotlin, Python, or Rust. This setup is closer to a practical maintenance task: moving old logic into a newer language with a larger ecosystem, while keeping behavior intact enough to pass tests.
Latest Results Show a Jump, Especially for Migration Work
The MultiLangBench numbers show a large gap between GPT-6 Astra and GPT-5.6 Terra. With maximum reasoning effort, GPT-6 Astra reaches an average test pass rate of 87.4 percent across the 20 languages. GPT-5.6 Terra is described as about 38 percent, and its listed score in the comparison is 37.9 percent.
OpenAI's chart credits the image to OpenAI and shows that GPT-6.1 Sol also reaches about 87 percent on MultiLangBench, matching GPT-6 Astra at that broad level. GPT-6 Luna scores 40.3 percent, barely ahead of GPT-5.6 Terra at 37.9 percent, but OpenAI notes it operates at a much lower cost.
The migration benchmark is where the newest result is most pronounced. GPT-6.1 Sol reaches 86.6 percent accuracy at low reasoning effort, compared with 5.4 percent for GPT-5.6 Sol. When reasoning effort is raised, GPT-6.1 Sol pushes accuracy to 97.9 percent.
Where the Progress Stands
The current state is a clear jump in measured capability, not a fully settled answer. OpenAI's evaluations show that GPT-6-class models can perform far better than GPT-5.6 models on selected low-resource programming tasks, particularly COBOL migration. The next question is whether high pass rates on database-building and translation benchmarks translate into dependable work across the many real systems that depend on older languages.
Comments
No comments yet. Be the first to comment.