
The Forward-Deployed Engineer Gym Is the Final Mile of AI Delivery
FDE-Gym tests AI agents on 95 ambiguous delivery tasks. Hidden constraints and customer metric movement, not raw facts, limit autonomous success.
Key Takeaways
- FDE-Gym tests AI agents on realistic forward-deployed engineer work, where vague customer requests, unstated constraints, and production-like system changes replace clean specifications.
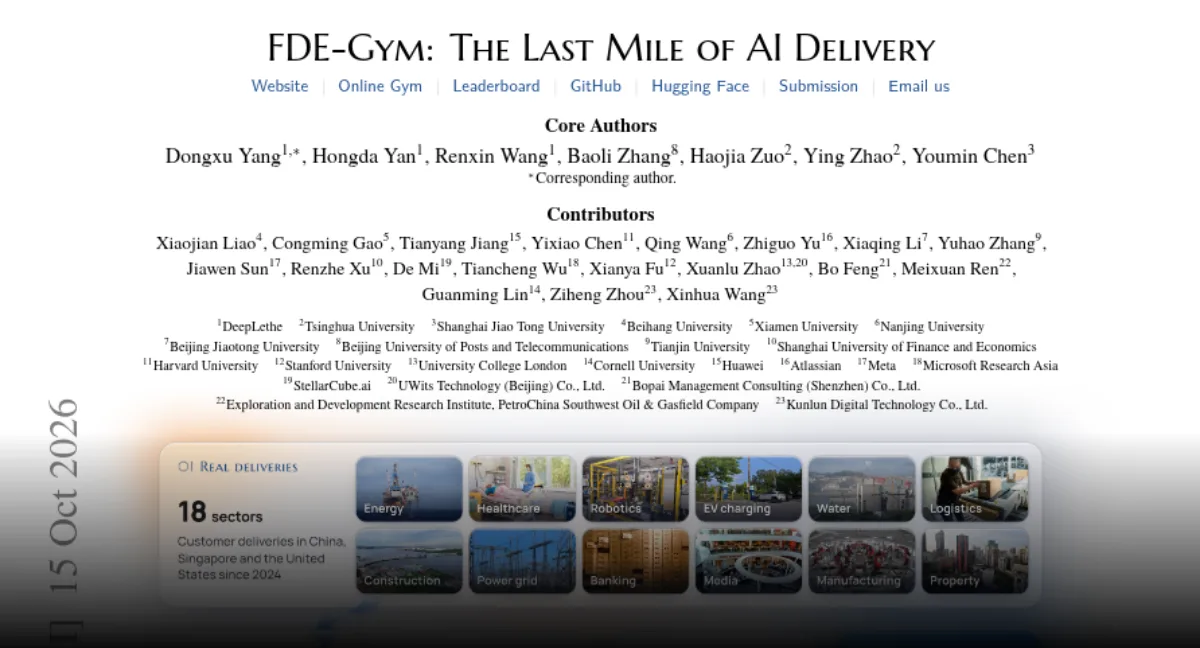
- The benchmark includes 95 end-to-end delivery tasks from 20 customer scenarios across 18 sectors, with success measured by improvement in the customer’s KPI on held-out data.
- The best model reaches a score of 0.56 and solves only 14 of 95 tasks, showing a large gap between current agent capability and reliable autonomous delivery.
- Hidden constraints are the main failure driver: even when models have all key facts, the best setup achieves 0.8 uplift on only 10 of 23 tasks.
- An upcoming human gym will compare human and AI performance, helping distinguish whether the challenge comes from delivery judgment itself or from how agents handle incomplete specifications.
Meta description: FDE-Gym tests AI agents on real delivery tasks. Best model scores 0.56, solves 14 of 95 tasks, and hidden constraints remain the main bottleneck.
Tags: AI agents, FDE-Gym, agent benchmarks, customer delivery, model evaluation
Featured image: abstract technology illustration of AI agents navigating ambiguous customer delivery workflows, no real people, no company logos, no text.
FDE-Gym places AI agents in the role of a forward-deployed engineer, a customer-facing technical worker who must deliver business value rather than complete a clean specification. The benchmark matters because it tests a skill current agentic systems often lack: turning a vague, sometimes misdirected customer request into a production-like change that improves the customer's key performance indicator, or KPI.
Background: The Gap Left by Existing Agent Benchmarks
Existing agent benchmarks usually provide a clear task and success criteria. Real delivery engagements do not. A sponsor may ask for the wrong outcome, important constraints may remain unstated, and success is judged by the customer's own business metric. FDE-Gym adapts that ambiguity into 95 end-to-end delivery tasks drawn from 20 customer scenarios across 18 sectors. Industry experts adapted the tasks from real projects, giving the benchmark a practical delivery shape rather than a clean specification.
Development: How FDE-Gym Tests Delivery Work
The setup changes three variables that ordinary benchmarks often keep fixed. First, agents must question scripted stakeholders, and asking is treated as costly, so curiosity is tested as a budgeted resource. Second, agents change production-like systems, which makes the task closer to real delivery work than to a one-off specification. Third, performance is measured by the delivered system's movement of the customer KPI on held-out data, where 0 represents the unchanged system and 1 represents an expert reference solution. Across 13 model configurations, the results show a clear gap between task completion and business impact.
Key Findings: Hidden Constraints, Not Raw Facts, Drive Failure
The main bottleneck is finding constraints that were never stated. Hiding those constraints costs leading models 0.28, while a misdirected request adds little extra loss. The top configuration reaches 0.56 while solving only 14 of 95 tasks. This result reframes what success means: even the best setup completes a small share of delivery scenarios, while still moving the customer metric by just over half of the expert reference.
The benchmark also separates information possession from successful delivery. With every key fact in hand, the best model reaches 0.8 uplift on only 10 of 23 tasks. That result suggests that facts alone do not guarantee a working delivery, because the agent still must make the right changes inside the production-like system and protect the customer metric. In some cases, weaker models leave the customer worse off than if nothing had changed, a practical warning for teams considering agent-driven delivery in high-stakes environments.
Latest Progress: Leaderboard and Human Gym
The current leaderboard is available at https://fde-gym.com/paper/#leaderboard. The next public milestone is an online gym for humans, which opens 1 November 2026. That addition gives the benchmark a comparative frame: if human performance is also exposed, readers can see whether the difficulty comes from delivery judgment itself or from the way current AI agents handle incomplete specifications and system changes. For now, FDE-Gym marks the stage where agent evaluation is moving from clean tasks toward customer delivery work, but the data still point to a large distance between model capability and reliable autonomous delivery.
Comments
No comments yet. Be the first to comment.