
Learning to Find Fascinating Mathematics
Automated mathematics is moving from proof verification to theorem selection. The new system gives large language models a measurable interestingness score, letting them generate, rank, and refine candidate theorems in a self-expanding loop. Reported gains show 4.3x higher interestingness, though correctness and novelty still require checking. The approach addresses a key bottleneck: human time spent deciding which mathematical statements deserve proof, especially as formal proof search becomes more capable.
Key Takeaways
- The article argues that theorem discovery in formal mathematics is shifting from proving known results to finding statements worth proving, with “interestingness” becoming a key bottleneck.
- It introduces a quantitative notion of interestingness, enabling a large language model to score and rank candidate theorems rather than only generating proofs.
- The system reports a 4.3× improvement in interestingness, indicating better selection of potentially valuable mathematical statements, not guaranteed correctness or novelty.
- A self-expanding discovery loop allows the model to generate, evaluate, and refine theorem candidates over time, reducing reliance on human-selected seeds.
Meta description: Large language model theorem discovery gains 4.3× interestingness through a quantitative notion and a self-expanding loop for formal mathematics.
Tags: Large language model theorem discovery, interestingness scoring, automated proof search, self-expanding discovery loop, formal mathematics
Featured image: abstract technology style network of proof nodes and edges, blue gradient, no real people, no company logos, no text
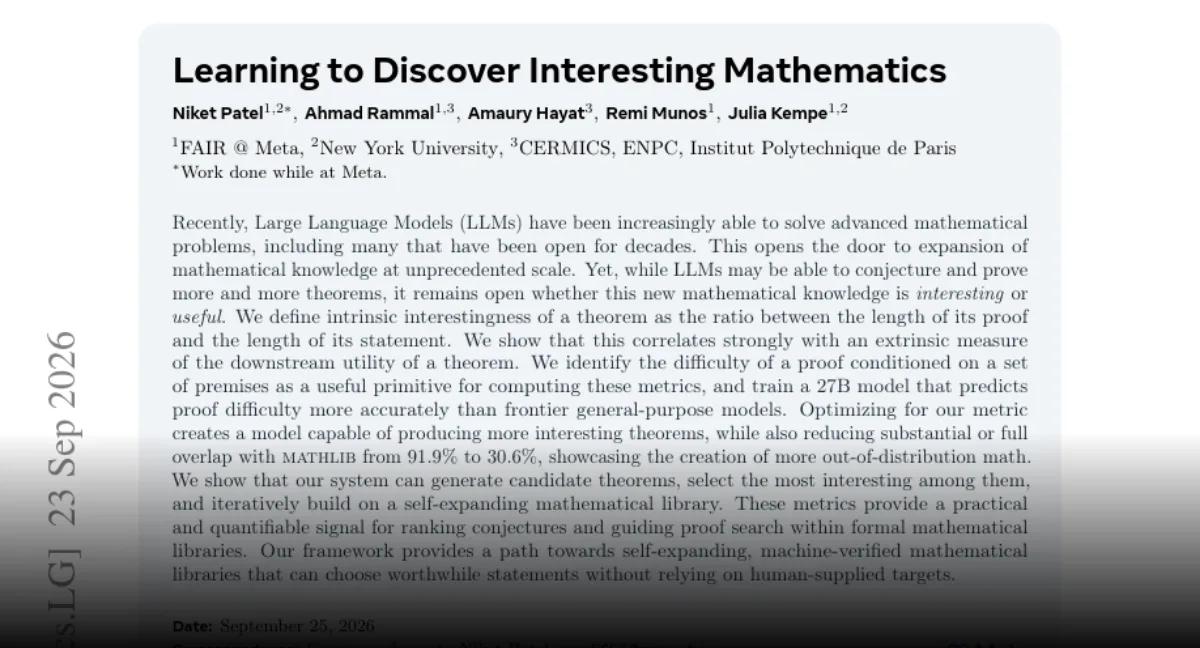
A large language model theorem discovery system is now at the center of a shift in automated mathematics: systems that once helped verify known proofs are being asked to find theorems worth proving. The latest development introduces a quantitative notion of interestingness, reports 4.3× higher interestingness, and describes a self-expanding discovery loop that could reduce human bottlenecks in theorem search.
Background: Results That Resisted Mathematicians for Decades
For decades, mathematical research depended on human intuition to choose problems. Formal theorem proving has advanced because proof assistants can check each logical step, but discovery of new statements has remained largely human. Recently, large language models, or LLMs, have begun to prove results that had resisted mathematicians for decades. That changes the pressure point: when proof search becomes easier, the scarce skill becomes deciding which theorem should be proved. The central claim is that finding interesting theorems without human guidance is a new bottleneck. This is important because many formal proofs may be valid but uninteresting, while the mathematical value of a statement depends on connections, generality, and relevance.
Development Process: Teaching a Large Language Model to Score Interestingness
The approach does not simply ask a model to generate random statements. It gives the model a quantitative notion of interestingness: a measurable target for deciding what counts as a theorem worth pursuing. By teaching an LLM to evaluate this target, the system can move beyond proof generation toward problem selection. The key step is converting a judgment that mathematicians usually make from experience into a score that a model can optimize. In practical terms, the model is not only asked to prove something, but to rank possible statements according to a numeric signal that approximates mathematical value.
Latest Progress: A Self-Expanding Loop and 4.3× Higher Interestingness
The headline number is 4.3× higher interestingness. That figure describes a gain in the model’s ability to identify statements judged more interesting, not a claim that every generated theorem is correct or novel. The more structural idea is the self-expanding discovery loop. Once a model can score candidate theorems, it can generate candidates, evaluate them, and use the strongest ones to shape the next search. Each cycle can broaden the pool of statements considered, making the process less dependent on hand-picked seeds. The loop is important because it addresses the bottleneck identified earlier: finding interesting theorems without human guidance.
What to Watch Next: Context and Limits
The current stage is not a replacement for mathematical taste, but a tool that can make taste measurable. The practical significance is for formal mathematics: if LLMs can propose higher-value statements, proof search may become more productive. Still, the value of a theorem depends on verification, novelty, and community relevance. Watch whether the 4.3× interestingness gain holds across domains, how the quantitative notion is defined and audited, and whether the self-expanding loop creates truly new formal results or mostly reshuffles known structures. The next phase will likely be measured by how many mathematical communities accept such machine-selected theorems as meaningful starting points.
Comments
No comments yet. Be the first to comment.