
Google's Gemini 4 Argon Is Nearer to the AI Frontier Than Any Google Model in Months
Gemini 4 Argon reaches 97.5% on ARC-AGI-3 with vendor features, yet drops to 49.8% under standard tests and trails rivals in math and software.
Key Takeaways
- Google DeepMind's Gemini 4 Argon scored 97.5% on ARC-AGI-3 under the Provider Adapter Harness, making it the second major AI lab to exceed 95% on this general problem-solving benchmark.
- The result is highly dependent on testing settings: in the Standard Harness, Argon fell to 49.8% and API issues affected completion of all games.
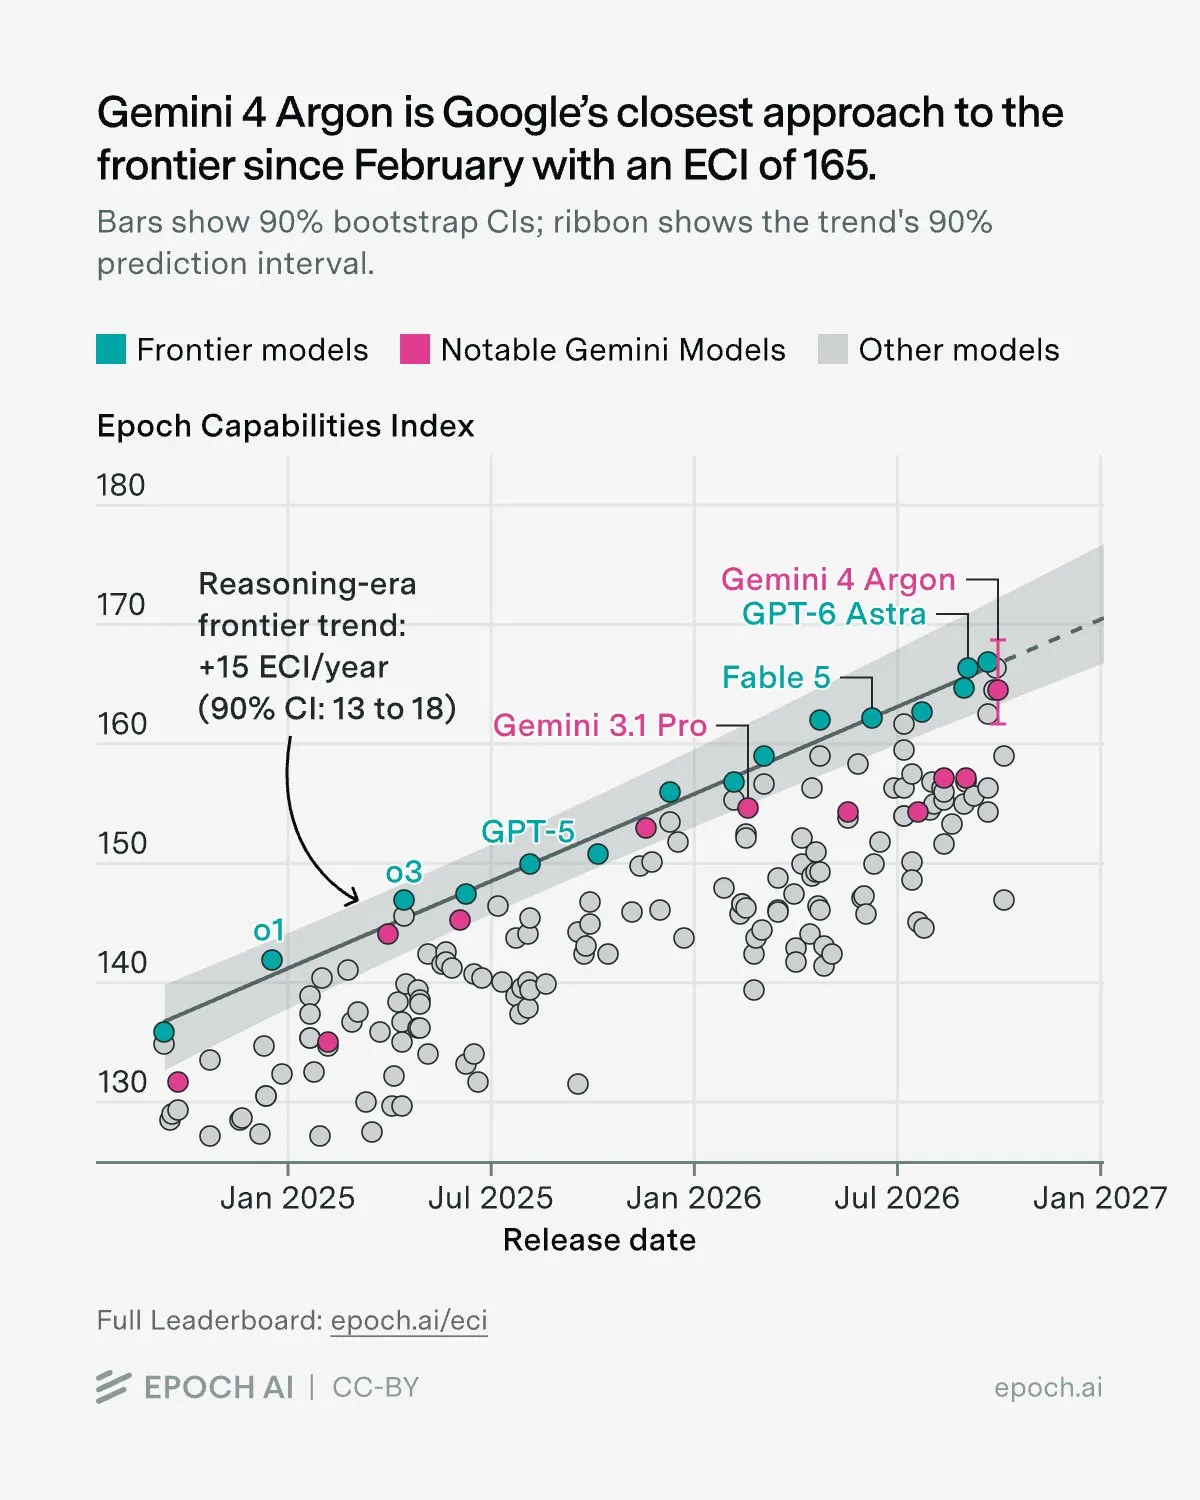
- On Epoch AI's composite capability index, Argon scored 165 points, bringing Google closer to the AI frontier than it has been since February 2026.
- Argon leads in some knowledge, agent, and vision benchmarks but still trails top models in math and software engineering.
- Overall, Gemini 4 Argon represents a major ARC-AGI-3 breakthrough for Google, but its frontier ranking requires careful interpretation of harness and evaluation conditions.
Google Deepmind Gemini 4 Argon Scores 97.5 Percent on ARC-AGI-3
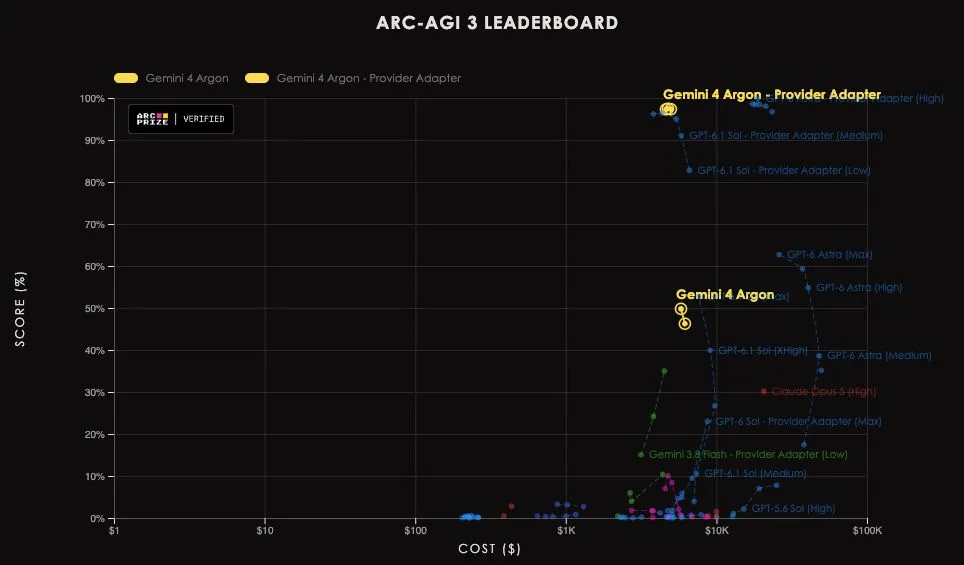
Google Deepmind has crossed a major problem-solving benchmark with Gemini 4 Argon, scoring 97.5 percent on ARC-AGI-3 at a cost of $4,800 under the Provider Adapter Harness. The result makes Google Deepmind the second major AI lab after OpenAI to pass 95 percent on ARC-AGI-3, which is widely considered the toughest benchmark for general problem-solving. But the score is tightly bound to the testing environment, and Epoch AI data shows Argon still trails top rivals in math and software engineering.
Background: ARC-AGI-3 scores hinge on harness settings
The dispute began in July 2026. OpenAI's GPT-5.6 Sol beat Claude Opus 5 on ARC-AGI-3 by using two API settings. In the Standard Harness, which only allows simple notes between rounds and discards internal reasoning after each action, GPT-5.6 Sol managed only 7.8 percent. That standard environment also used an older interface lacking newer Claude API features, meaning Claude was tested under different conditions than GPT-5.6 Sol. When OpenAI's own Responses API was used, with Retained Reasoning and smart context Compaction, GPT-5.6 Sol jumped to 38.3 percent and beat Claude Opus 5 at 30.2 percent. OpenAI argued that benchmarks always measure the technical environment too. ARC Prize co-founder Francois Chollet then allowed general, publicly available API settings.
Development: Google Deepmind enters the 95 percent tier
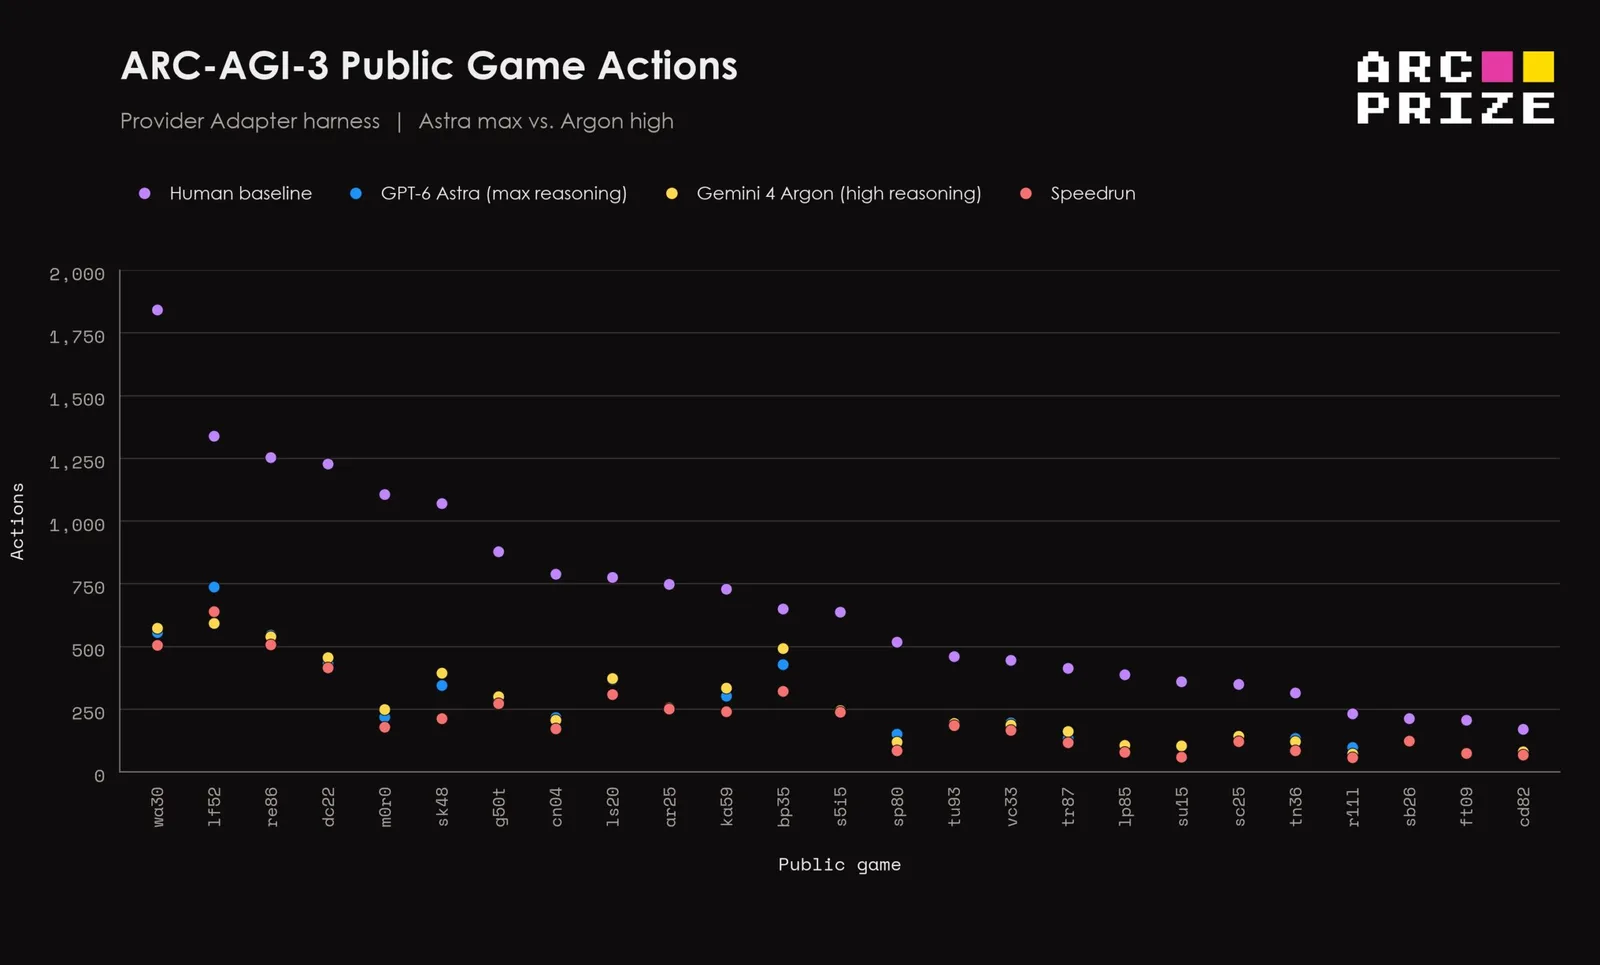
Under the Provider Adapter Harness, which uses vendor-specific features such as retained reasoning and context compaction, Gemini 4 Argon scored 97.5 percent at $4,800. Only GPT-6 Astra scores higher at 99.9 percent. Across the 25 public games of ARC-AGI-3, Gemini 4 Argon and GPT-6 Astra both needed 62 percent fewer actions than the human baseline and often came close to the speedrun record. Argon matched or beat the speedrun record in three games and came within 10 percent of the best time in six others. On older versions, Argon scored 91.3 percent on ARC-AGI-2 at $0.32 per task and 98.5 percent on ARC-AGI-1 at $0.16 per task, based on introductory prices of $2 per million input tokens and $10 per million output tokens.
The high score is not the whole story. In the Standard Harness, Argon dropped to 49.8 percent at low reasoning for $5,800. API problems also prevented Argon from completing all 55 games in the Standard Harness, according to the testers. At low reasoning, the system finished 42 games for 49.8 percent; at medium it finished 46 games for 46.3 percent; at the highest level it completed 19 games, so ARC Prize did not publish a score. The reported results still covered all 55 games by including partial points from aborted runs.
Latest: Epoch AI places Argon near the frontier but behind in math and software engineering
Epoch AI tracked Google's progress. Argon scored 165 points on the Epoch Capabilities Index, tying Fable 5.1 and landing just behind Opus 5.5 at 167 and GPT-6 Astra at 166. The ECI combines over 50 benchmarks into a single capability scale, similar to how Artificial Analysis builds its main score. With an ECI score of 165 points, Google is closer to the current AI frontier than it has been since Gemini 3.1 Pro in February 2026. Argon also jumps ahead of Gemini 3.8 Flash at 157 points, a trend Artificial Analysis and Vals.ai had confirmed earlier.
Performance varies by domain. According to Epoch AI, Argon leads several knowledge, agent, and vision benchmarks, but early estimates put it in eighth place on the Math ECI and sixth place on the Software Engineering Index, known as SWE ECI. The current stage is therefore mixed: Gemini 4 Argon reaches the top tier on ARC-AGI-3 under a vendor-feature harness and narrows Google's gap to the frontier on Epoch AI's composite index, but its ranking depends on whether API settings, reasoning controls, and aborted runs are counted consistently, and it still trails the leaders in math and software engineering.
Comments
No comments yet. Be the first to comment.