
TokenRouter: An Efficient Serving Framework for Token-Level LLM Routing
TokenRouter proposes token-level routing for LLM serving, moving control from whole requests to tokens for finer scheduling and resource optimization.
Key Takeaways
- TokenRouter proposes an LLM serving engine that shifts control from request-level routing to token-level routing.
- Token-level routing enables finer-grained management of inference by directing individual tokens or token groups within a serving system.
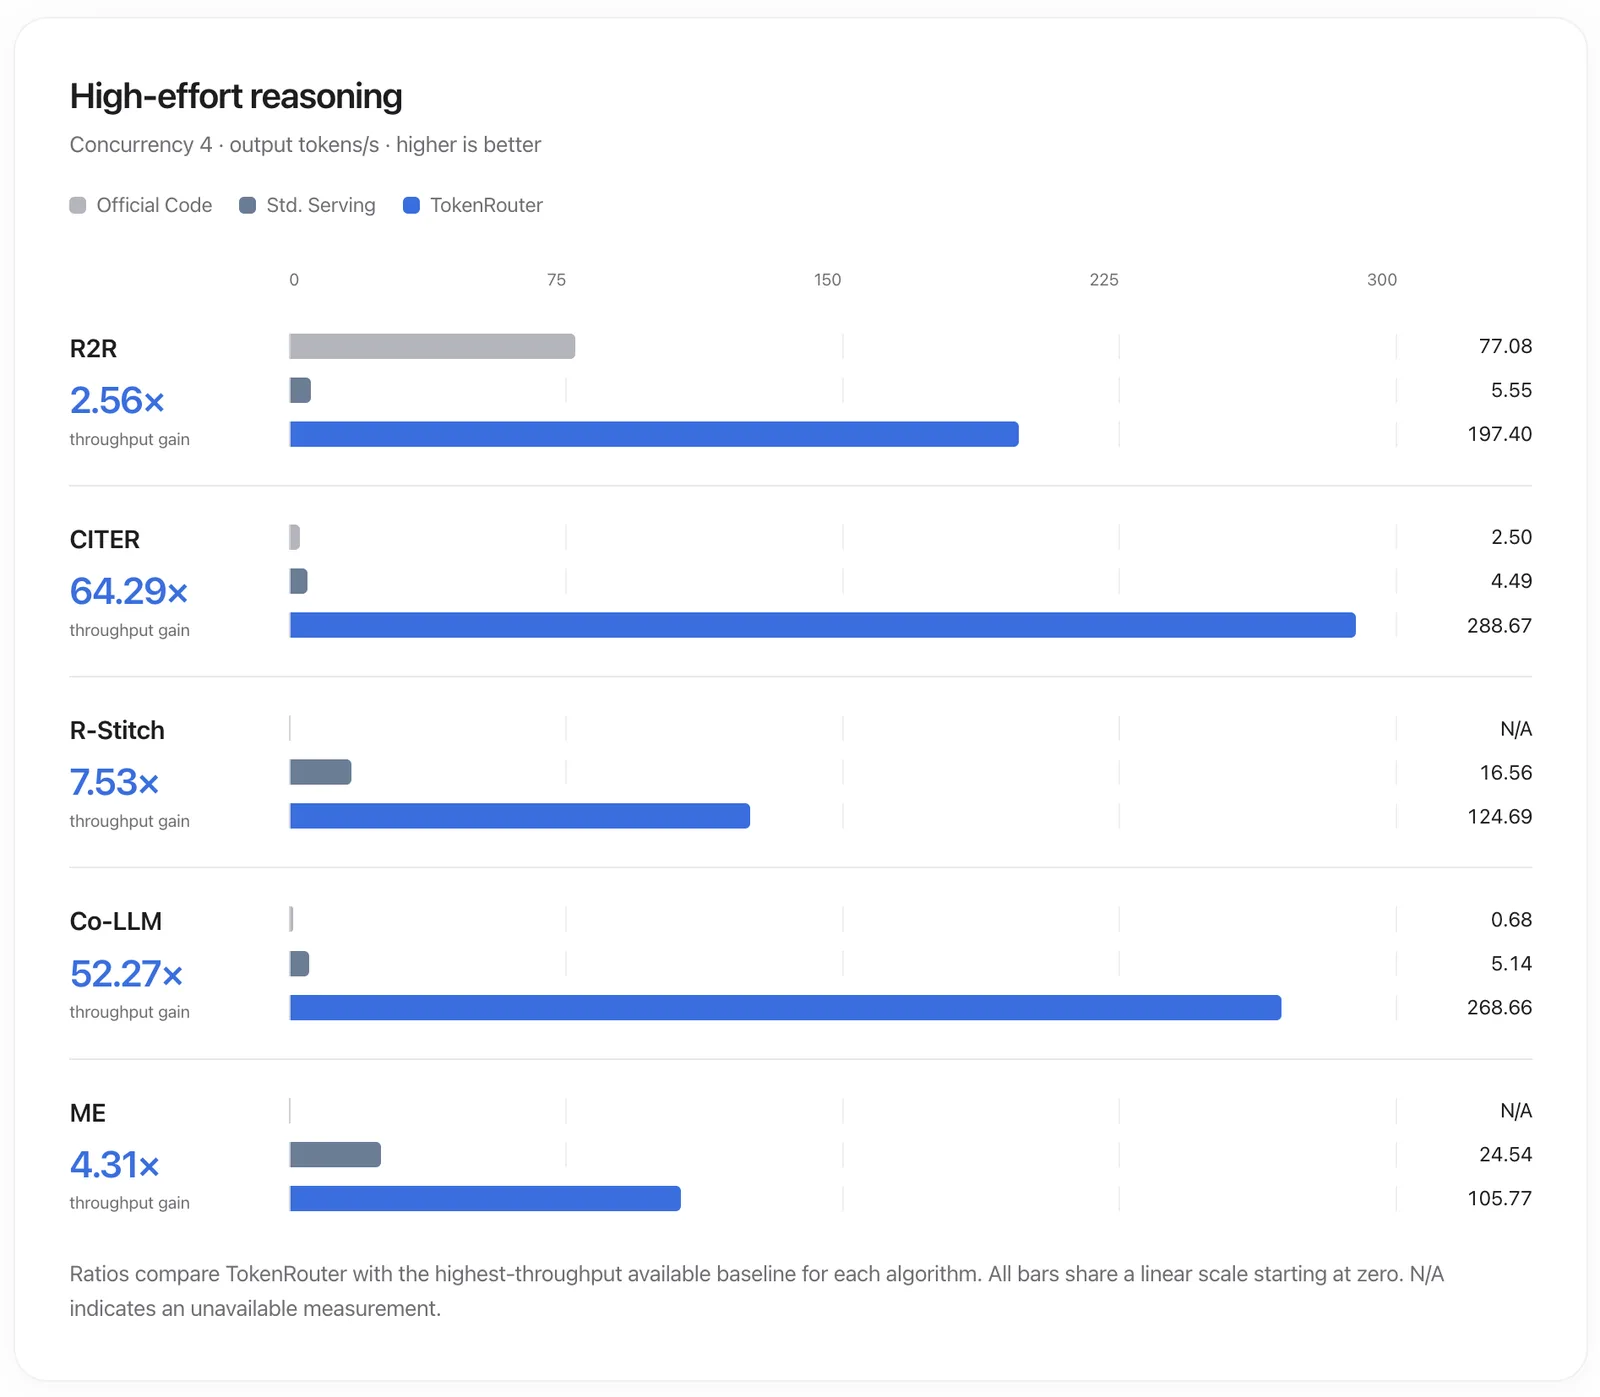
- The article emphasizes this as an infrastructure design change rather than a confirmed performance improvement, since no benchmarks or efficiency numbers are provided.
- Practical value depends on implementation quality, scheduling overhead, batching, memory management, and compatibility with existing LLM serving stacks.
- TokenRouter represents an early-stage direction in AI infrastructure where the token becomes a manageable unit of serving control.
Meta description: TokenRouter presents an efficient LLM serving engine for token-level routing, pointing to finer-grained control in large model serving workflows.
Tags: TokenRouter, LLM serving, token-level routing, AI infrastructure, inference engine
Featured image: abstract technology style, blue and violet neural network pathways branching through a translucent server grid, no people, no logos, no text.
TokenRouter is presented as an efficient LLM serving engine for token-level routing. That single sentence frames a practical shift in AI infrastructure: large language models are no longer served only as whole applications, but are broken into smaller execution units that can be directed, scheduled, or assigned across a serving system. The significance is not a new benchmark or a released product name alone; it is the move toward finer control over how model tokens are handled during inference.
Background: Serving Moves From Whole Requests to Tokens
LLM serving systems usually begin with a request-level view. A user sends a prompt, a model generates tokens one by one, and the system manages compute, memory, and response time around the request as a unit. Tokens are the basic pieces of text a model sees and produces, so routing decisions traditionally happen before generation or at coarse stages such as choosing a model, a worker, or a cache.
As inference becomes more central to products and services, that coarse view creates pressure. Different parts of a prompt or different stages of generation may need different resources, models, or handling strategies. A serving engine that only routes whole requests can leave useful control points unexamined. TokenRouter appears in this context as a proposal for an engine built around token-level routing rather than request-level routing alone.
Development: Why Token-Level Control Became a Pressure Point
The practical value of token-level routing lies in granularity. If routing can operate at the token level, a system may be able to direct individual tokens, or token groups, through paths suited to their role in a larger workload. This does not automatically prove faster performance or lower cost, and no efficiency numbers are provided, but it changes the design question from “which model answers this request?” to “how should each token be handled as the request unfolds?”
Such a shift matters because serving engines sit between users and model weights. They decide where compute is allocated, how requests are batched, which cache is consulted, and how traffic is balanced. Token-level routing gives those decisions a smaller decision unit. In theory, smaller units can expose more room for optimization. In practice, the benefit depends on implementation quality, overhead, scheduling complexity, and compatibility with existing LLM serving stacks.
Latest Progress: TokenRouter Presents an Engine for the New Granularity
The current presentation of TokenRouter identifies it as an efficient LLM serving engine for token-level routing. The wording positions the project within infrastructure, not model training or application design. It suggests a serving layer intended to manage token flow inside LLM deployments, where routing choices may influence throughput, latency, resource use, or operational control.
No specific date, company, benchmark, or performance figure is included in the source material, so the most defensible reading is that TokenRouter is an early-stage system concept aimed at a concrete serving problem. The contribution is the routing abstraction itself: moving the unit of control closer to the token, the basic unit through which LLMs generate and process language.
What to Watch Next
The next question is how token-level routing is implemented in a serving engine without adding excessive scheduling overhead. Efficient LLM serving depends on batching, memory management, model execution, and network coordination. If TokenRouter can make token-level decisions while preserving these system properties, it may become useful for deployments where prompts, models, or token paths need more precise separation.
At this stage, the project represents a direction in AI infrastructure rather than a fully evaluated product launch. It points to a serving model where the token, not only the request, becomes a manageable unit of control.
Comments
No comments yet. Be the first to comment.