
OpenAI to Add Watermarks to ChatGPT Outputs in the EU, While Making Them Optional for API Users Globally
OpenAI will add textGrain watermarks to ChatGPT and Codex in the EU, while API watermarking stays opt-in worldwide; edits sharply reduce detection.
Key Takeaways
- OpenAI will add invisible textGrain watermarks to ChatGPT and Codex outputs in the EU to comply with the EU AI Act’s machine-readable AI labeling requirements.
- Watermarking will be mandatory for EU consumer products, but API watermarking is opt-in worldwide, unlike Anthropic’s globally mandatory approach.
- textGrain detection performance depends on text length and topic, and is sharply weakened by editing: replacing 25% of words can drop detection below 20%.
- OpenAI says watermarking does not reduce output quality, but a detected watermark does not prove human authorship, ownership, accuracy, or the extent of editing.
- Detector access is currently limited to selected researchers and specialist organizations, and will only reveal whether an OpenAI watermark is present without exposing user or prompt details.
Meta description: OpenAI will add textGrain invisible watermarks to ChatGPT and Codex in the EU, while API watermarking remains opt-in worldwide for developers.
Tags: OpenAI, textGrain, EU AI Act, ChatGPT, AI watermarking
Featured image: abstract network of text tokens forming a hidden watermark pattern, no real people, no company logos, no text.
OpenAI is adding an invisible textGrain watermark to ChatGPT and Codex output in the European Union, a move tied to the EU AI Act and a machine-readable labeling requirement for AI-generated text. Unlike Anthropic, whose Claude watermarking is mandatory worldwide regardless of how users access the models, OpenAI says its API watermarking will be opt-in for developers around the globe.
Background: EU rules push machine-readable AI text labels
The EU AI Act reportedly requires AI providers to label generated text in a machine-readable format. OpenAI's answer is textGrain, which embeds an invisible statistical signal in the model's word choices. The approach is similar to Claude's SynthID watermark, which uses Google's open-source technology. For readers, the change means that text generated through ChatGPT or Codex in the EU may carry a hidden signal that can be checked by specialized detectors, even when the text looks normal to humans.
Development: OpenAI deploys textGrain with different access model
OpenAI says it will turn on watermarking for ChatGPT and Codex users in the European Union over the coming weeks. API watermarking will be opt-in worldwide, and it will also be available through cloud partners such as Microsoft Azure in the coming weeks. That choice separates OpenAI's rollout from Anthropic's global, mandatory approach and gives API customers more control over whether generated text is marked. OpenAI also plans to release textGrain as open source so other parties can build on it.
Latest progress: Detection depends on length, topic, and edits
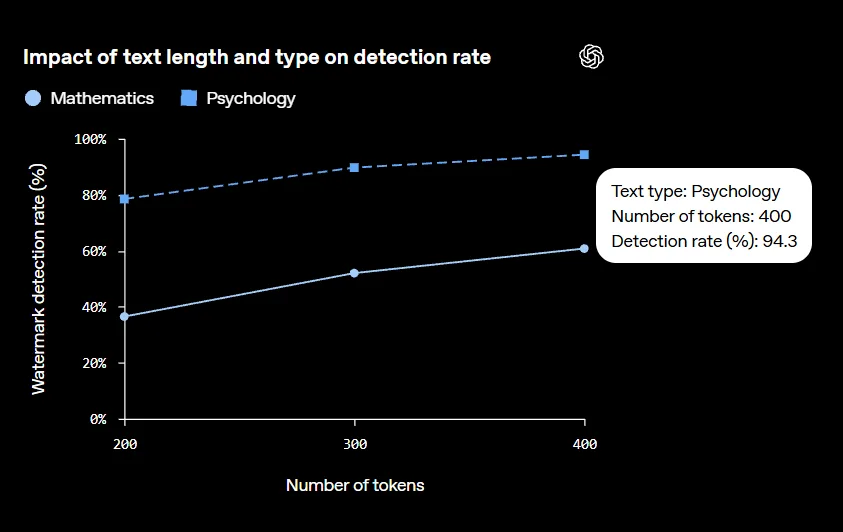
In internal tests, OpenAI says textGrain matched or beat other approaches, including Google's SynthID for text. Detection rates depend heavily on text length and subject matter. With a detector set to a target false-positive rate of 1 percent, it identified watermarks in about 95 percent of 400-token passages about psychology. At 200 tokens, the rate fell to about 80 percent. OpenAI's published illustration also describes 400-token passages, roughly 300 words, as reaching about 94 percent detection for psychology text and only about 60 percent for math text. The company says math content is harder because the model has less freedom to choose words. Longer passages might strengthen the statistical signal and improve detection, but OpenAI provides no data to test that assumption.
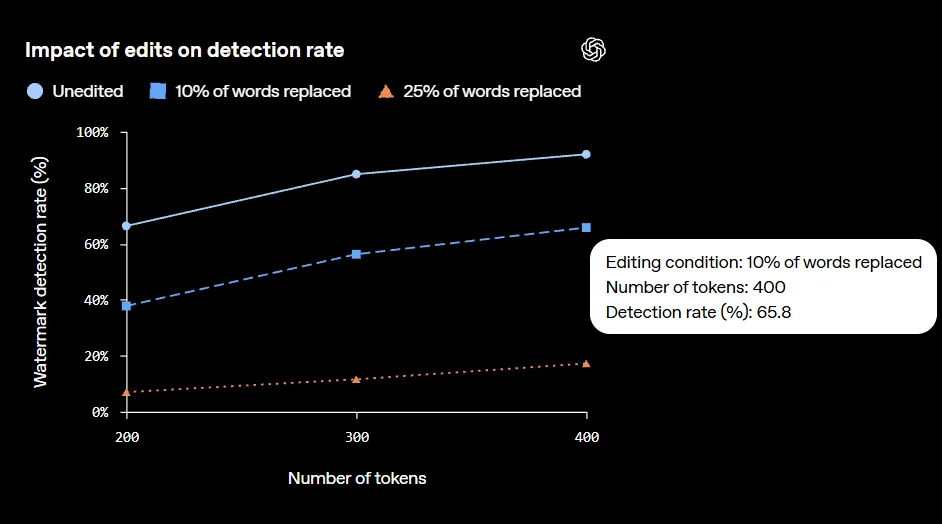
Editing sharply reduces detection. Replacing just 10 percent of words with synonyms cuts detection rates for 400-token passages from about 92 percent to 66 percent. Replacing a quarter of the words drops detection to 17 percent, and OpenAI notes that replacing 25 percent pushes detection below 20 percent even in 400-token passages. That weakness could push users who do not want detected ChatGPT use toward open-weight models. Anthropic has not published detection rates for Claude's watermark, though it says its system holds up well against edits.
Current stage: Limited detector access and open verification tools
OpenAI says watermarking does not hurt output quality, citing tests of its frontier model Astra. The company reports no significant performance differences with watermarking on or off across eight benchmarks, including GPQA Diamond, BrowseComp, and DeepSWE. Those results do not establish whether watermarking affects writing quality, a concern critics have also raised about Claude's watermark. OpenAI adds that a detected watermark reveals nothing about human creativity or editing, does not establish ownership, assign responsibility, identify a user, or show whether text is accurate. Failure to detect a watermark also does not prove a human wrote the text; it could be too short, edited, translated, or from an unsupported model.
For now, only selected researchers and specialist organizations can access textGrain's detector through an application form. OpenAI will grant access case by case under the EU's Code of Practice, while Anthropic takes a similar approach with its detection API. The tool will report only whether it detected an OpenAI watermark and will not identify users or reveal prompts or conversations. OpenAI says access is limited because the detector can flag unmarked text or miss watermarks, and it plans to expand access when results can be interpreted responsibly, without giving a date. Existing verification tools for images and audio remain publicly available, including openai.com/verify and the Content Provenance API. The next test is whether a machine-readable label can remain meaningful when editing, model choice, and jurisdiction all shape whether text is marked or detected.
Comments
No comments yet. Be the first to comment.