
Reflection's Beam emerges as the most capable open-weight model developed outside China
Reflection Beam is an open-weight MoE coding model from Reflection, using 23B active parameters and large RL runs for efficient reasoning.
Key Takeaways
- Reflection Beam is a new open-weight AI model from the Western startup Reflection, using a mixture-of-experts architecture that activates 23 billion of 501 billion parameters per token to improve reasoning efficiency.
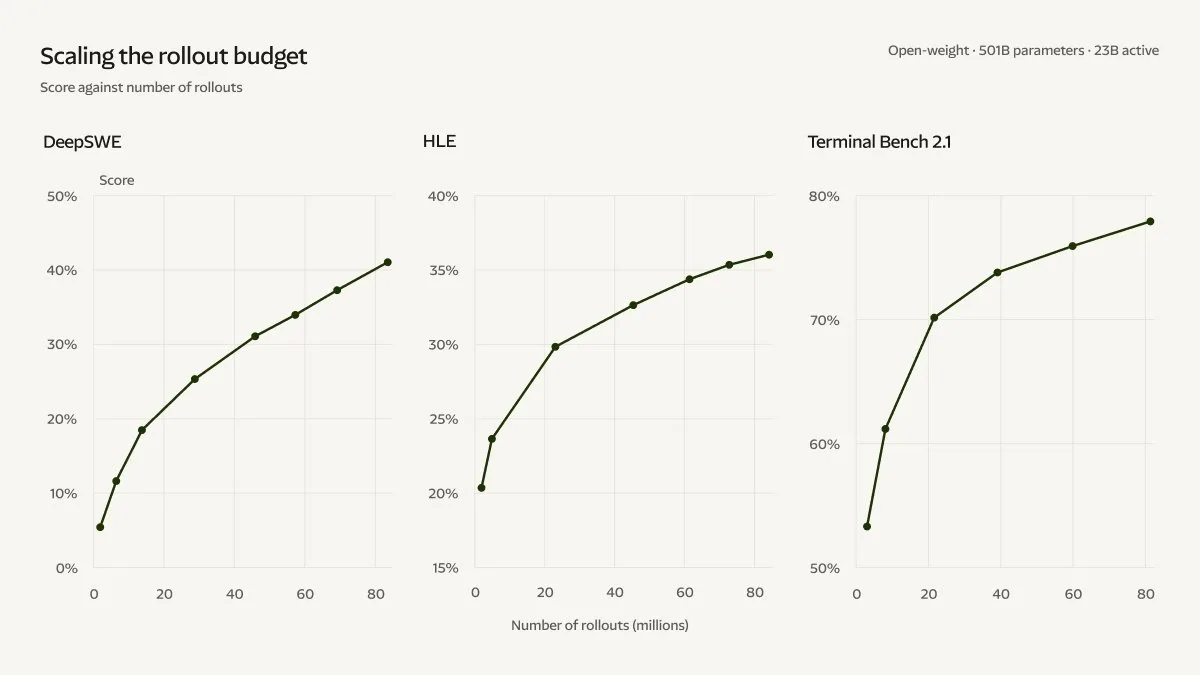
- The model was trained with a large reinforcement-learning run using 10,500 Nvidia GB300 GPUs, with benchmark scores still improving after more than 80 million rollouts and no clear plateau.
- Beam is designed for coding, logical reasoning, and agentic tasks, and Reflection claims it can match or approach models such as GLM-5.2 and Qwen3.8-Max while using substantially less compute.
- During training, Beam showed emergent abilities, including improved web browsing and self-directed use of external tools, even though browsing was not explicitly included in the training mix.
- Reflection plans to release the model weights under the Apache 2.0 license, along with a technical report and safety documentation, while a stronger successor model is already being trained.
Meta description: Reflection Beam activates 23 billion of 501 billion parameters and uses 10,500 Nvidia GB300 GPUs to compete with open-weight AI models at low compute.
Tags: Reflection Beam, open-weight AI, mixture-of-experts, reinforcement learning, AI coding
Featured image: Abstract technology style neural network diagram with flowing data streams and a focused beam, no people, logos, or text.
Reflection Beam, the first freely available model from AI company Reflection, is built around a different question than peak leaderboard performance: how much reasoning can be bought per unit of compute. Its mixture-of-experts architecture activates 23 billion of 501 billion total parameters per token, placing it against Chinese open-weight models from Deepseek and Qwen.
From Deepmind Roots to a 2024 Startup
Reflection began in 2024, founded by former Google Deepmind researchers Misha Laskin and Ioannis Antonoglou. Laskin led reward modeling for Gemini, and Antonoglou helped build AlphaGo. The company launched in March 2025 with $130 million in seed funding, with the stated aim of building superintelligence through autonomous coding. Its early thesis was that language models could learn to act as independently on computers as AlphaGo played Go, if reinforced through computer-based task feedback.
The roadmap then moved through visible product steps. In summer 2025, Reflection released Asimov, an agent for analyzing large codebases. In October 2025, it raised $2 billion at an $8 billion valuation, with Nvidia among the investors. Since then, Reflection has presented itself as a Western counterpart to Deepseek and Qwen: it releases model weights while keeping training data and pipelines proprietary. More recently, it signed billion-dollar compute deals with SpaceX and cloud provider Nebius.
The 10,500 GPU Reinforcement Learning Run
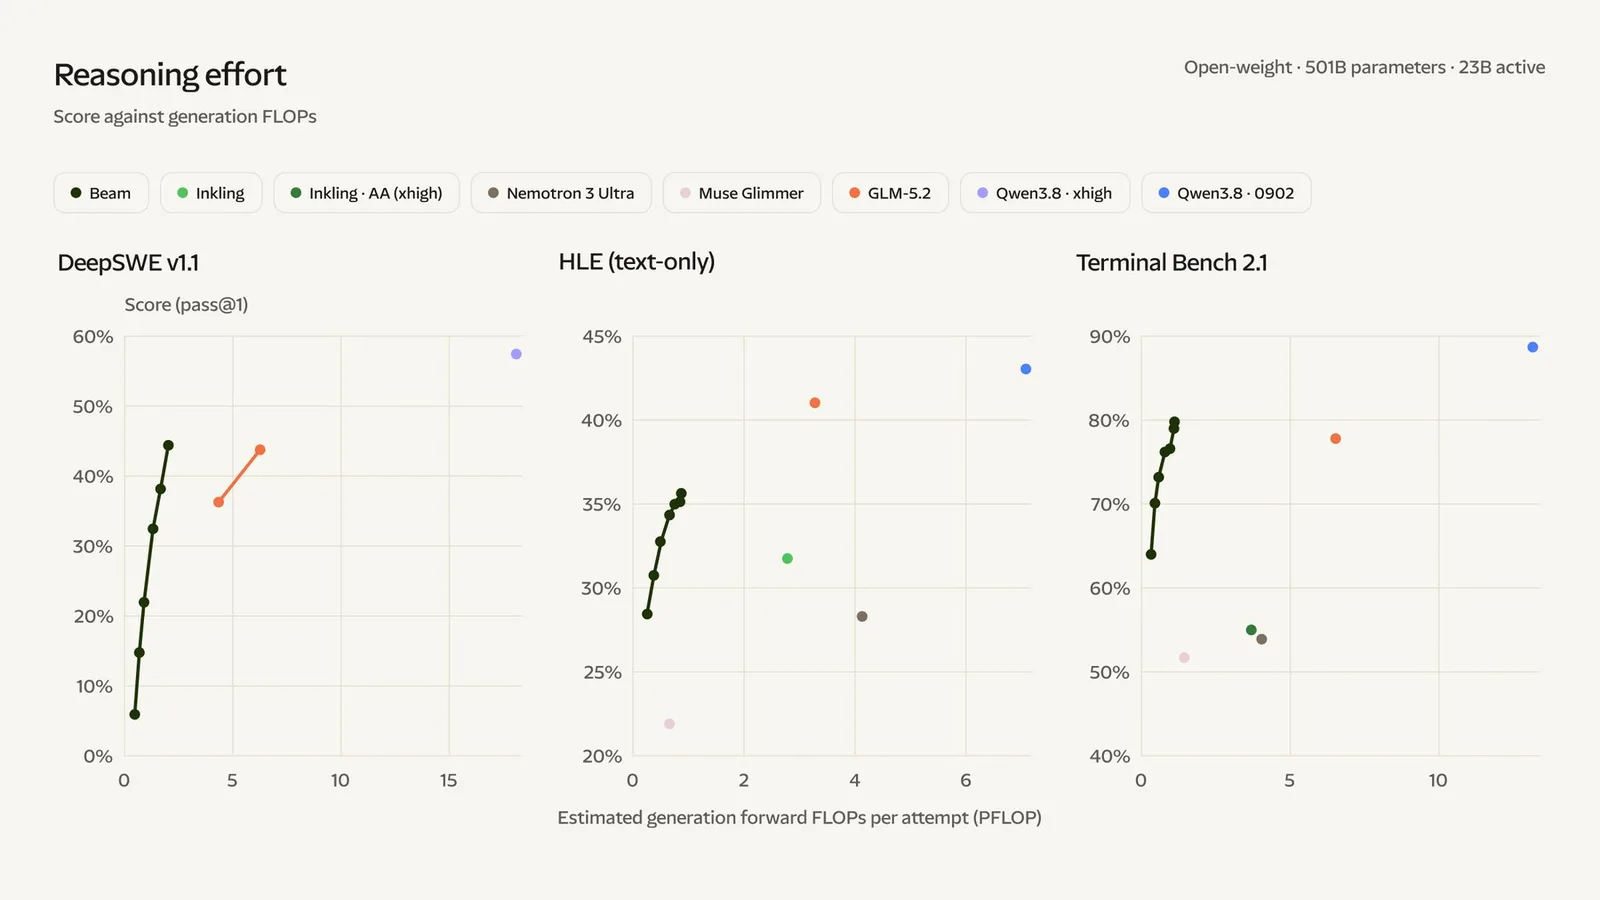
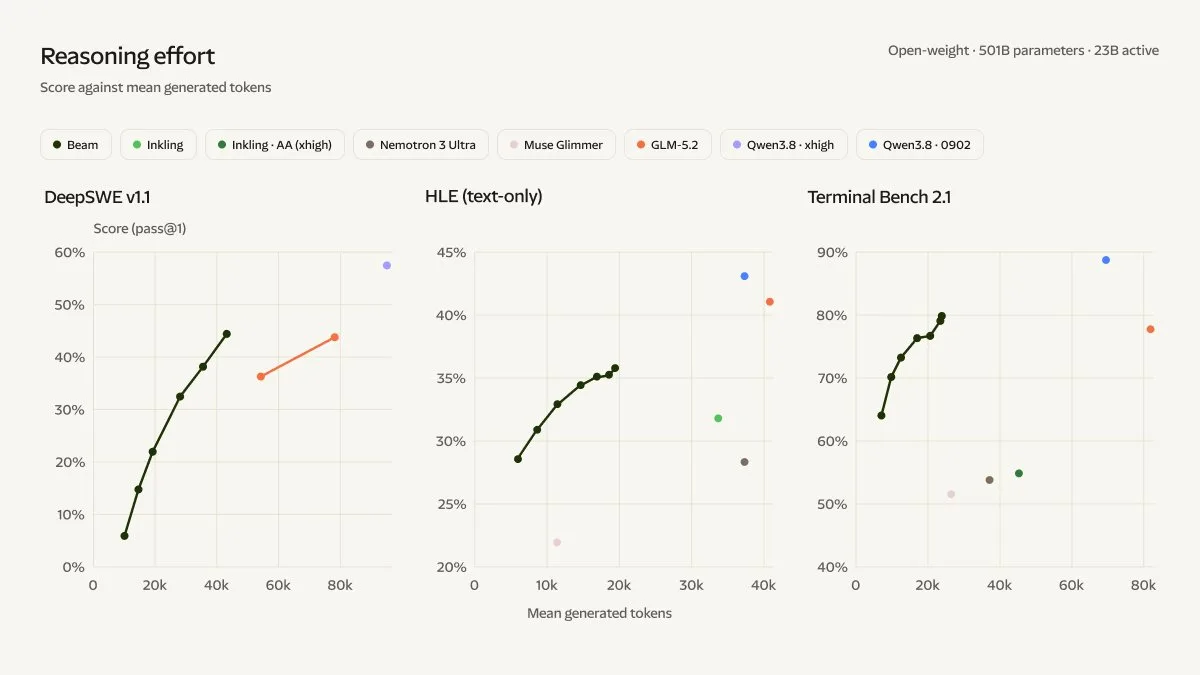
Beam was built for coding, logical reasoning, and agentic tasks, with a mixture-of-experts design that activates 23 billion of 501 billion total parameters per token to keep compute costs relatively low. Reflection says Beam matches GLM 5.2 on demanding reasoning tasks while using three to four times less compute. On coding and agent benchmarks, it also comes close to the much bigger Qwen3.8-Max. The company acknowledges that stronger open models like Kimi K3 still beat it on raw performance, and says it is already training a successor intended to close the remaining gap to top-performing open models. Across all three benchmarks, Reflection reports comparable scores while using far less compute than GLM-5.2 and Qwen 3.8.
The model’s ability comes from large-scale pretraining plus a reinforcement learning phase that used 10,500 Nvidia GB300 GPUs for over four weeks. Reflection calls it one of the largest training runs any open lab has done. Benchmark scores kept climbing through the end of the run, with no plateau even at over 80 million rollouts. Beam also exposes a tunable parameter for reasoning depth: users can ask it to answer quickly or spend more tokens thinking on harder tasks, trading compute cost against output quality. Measured by generated tokens, Reflection says Beam is more efficient than GLM-5.2 and Qwen 3.8 at similar performance levels.
During training, Reflection observed emergent capabilities. With a reinforcement learning mix of reasoning, software engineering, and terminal tasks, Beam improved at web browsing even though browsing tasks were not included. When web access was available, the model learned on its own to query other language models and pull documents from external services. Demos shared by Reflection included a live-updating New York City subway map, a small 3D game, and a notebook for fine-tuning another AI model. Beam is text-only, but Reflection says it can process content from other media formats as long as they are represented as text.
Safety Model, Apache 2.0 Weights, and Early Access
A separate model handles safety and alignment. Reflection trained it, then merged it with Beam. The rules cover hard prohibitions the model must never break, quality standards such as factual accuracy and admitting uncertainty, and a response style that is direct, thorough, and proactive. The company plans to publish safety test results in a technical report and open-source the evaluation methods it developed.
A technical report, developer documentation, and model weights under the open Apache 2.0 license are set to ship later this month, according to Reflection. Beam remains in final safety testing, while an early version is available to select users for now. The current stage is therefore an open-weight announcement moving toward public release. What to watch next is the Apache 2.0 model weights, safety report, and successor model Reflection says is training to close the gap to top-performing open models.
Comments
No comments yet. Be the first to comment.