
When Reasoning Alone Is Insufficient: Guiding Small Models to Think Beyond Parametric Knowledge
FlyBy helps small reasoning models by separating execution and knowledge bottlenecks and using selective external queries to keep reasoning accurate.
Key Takeaways
- Small reasoning models can fail despite longer reasoning because of two distinct issues: execution bottlenecks, where the correct next step is internally reachable but not found, and knowledge bottlenecks, where the needed facts are missing from the model’s parameters.
- FlyBy is a framework that learns when to ask stronger external models for help and how deeply to query them, then integrates the returned information into the smaller model’s own reasoning path.
- The approach is selective rather than indiscriminate: it aims to keep compact models in control while using external knowledge only when the failure is likely due to missing information.
- For practitioners, FlyBy can reduce costly calls to large models, preserve speed, and encourage evaluating reasoning failures by type, not only by final accuracy.
- The article does not provide benchmark results or deployment numbers; the key open question is how reliably a small reasoning model can decide when to query externally and when to continue alone.
Meta description: FlyBy explains why small reasoning models fail despite extended reasoning and uses selective external queries to address execution and knowledge bottlenecks.
Tags: small reasoning models, FlyBy, query-augmented reasoning, execution bottleneck, knowledge bottleneck
Featured image: Abstract network of small nodes querying larger nodes, technology style, no real people, no company logos, no text.
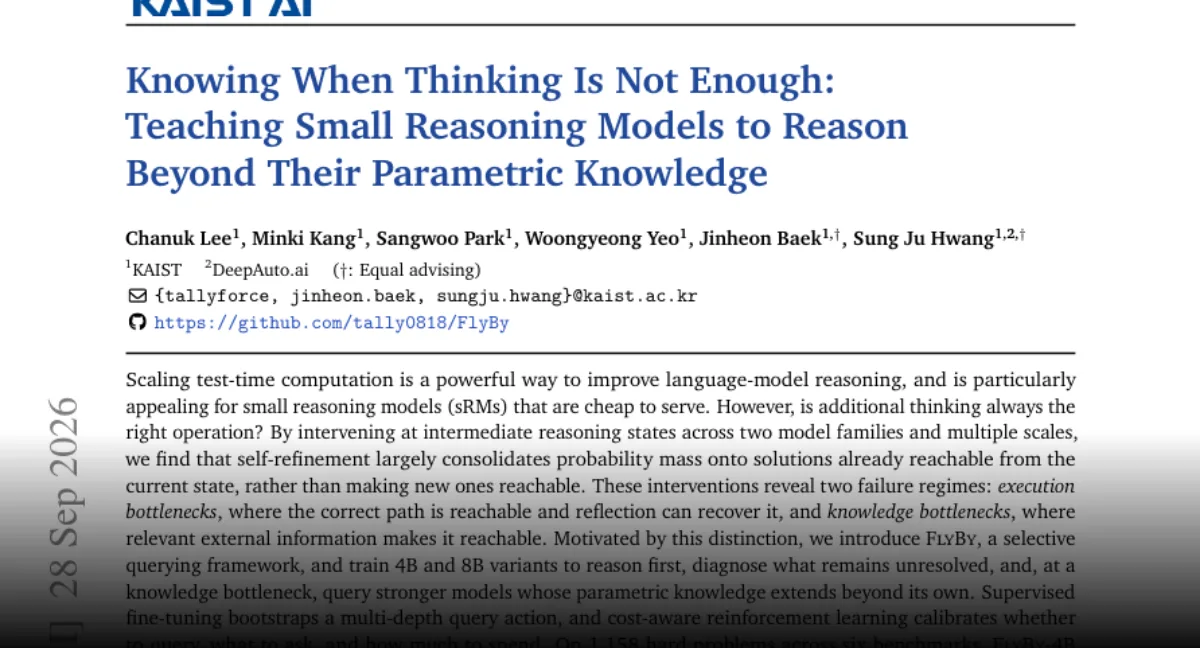
A framework called FlyBy addresses why small reasoning models can fail even when they are allowed to reason for longer. The work separates two causes: execution bottlenecks, where the correct next step is still reachable inside the model, and knowledge bottlenecks, where missing parametric knowledge blocks progress. FlyBy then learns when to ask stronger external models for help and how deeply to query them, using the returned information to continue its own reasoning instead of calling external models indiscriminately. This is relevant for teams that want compact models to remain useful on difficult tasks without paying the cost of every possible external call.
Background: Extended Reasoning Does Not Guarantee Correct Answers
Small reasoning models are attractive because they can be faster, cheaper, and easier to deploy. But when a task requires many inference steps, a compact model may enter a failure mode that looks like a reasoning problem even though the underlying cause differs. In one case, the model may already contain enough information to continue, but its reasoning process does not find the correct continuation. In another, the model simply lacks the needed facts or structured knowledge in its parameters. Without distinguishing these cases, extended reasoning can produce long, confident, but wrong outputs.
Development: Separating Execution Bottlenecks From Knowledge Bottlenecks
The research contribution is the split between execution bottlenecks and knowledge bottlenecks. An execution bottleneck is internal: the right continuation remains reachable, but the model does not retrieve or construct it during reasoning. This suggests that more compute inside the same model may help if the search process is improved. A knowledge bottleneck is different: the missing information is not available in the model’s parametric memory, so no amount of internal reasoning can invent the needed fact.
That distinction explains why simply scaling reasoning time can fail. It also creates a design target: systems need a way to detect when external knowledge is required, and when the problem is merely internal search difficulty.
Latest: FlyBy Uses Selective Queries Instead of Constant External Calls
FlyBy turns that diagnosis into a selective query-augmented reasoning framework. Rather than routing every question to a stronger model, it learns when a query should be made and how deep that query should go. In principle, query depth can range from a brief lookup to a more substantial retrieval, depending on how much missing information the model needs before it can resume its own reasoning. After receiving external output, FlyBy integrates it into the smaller model’s reasoning path.
The goal is to combine the lower cost of a small model with the knowledge breadth of stronger external models while avoiding indiscriminate querying. This keeps the smaller model in control of the reasoning process, but allows it to call for help only when the failure is likely caused by missing knowledge rather than weak internal search.
What This Means for Compact Reasoning Systems
For practitioners, the main value is cost control. Selective querying can reduce calls to expensive large models, preserve response speed, and keep small models in charge of most reasoning. The approach also suggests that future reasoning systems should evaluate failures by type, not only by final accuracy. A low score may reflect poor internal search, missing knowledge, or excessive reliance on external calls.
The current source material describes the framework and the bottleneck categories, but it does not provide dates, benchmark scores, model sizes, or deployment results. The next stage of scrutiny will be whether learned query policies improve accuracy enough to justify added system complexity. The field is currently at the stage of proposing a mechanism rather than showing public performance numbers. The key open question is how reliably a small reasoning model can decide when to query and when to continue alone.
Comments
No comments yet. Be the first to comment.